js中的正则表达式 使用Docker和Elasticsearch搭建全文本搜索引(9)
电脑杂谈 发布时间:2018-02-22 10:22:50 来源:网络整理awaitesConnection.client.bulk({ body: bulkOps })
bulkOps = []
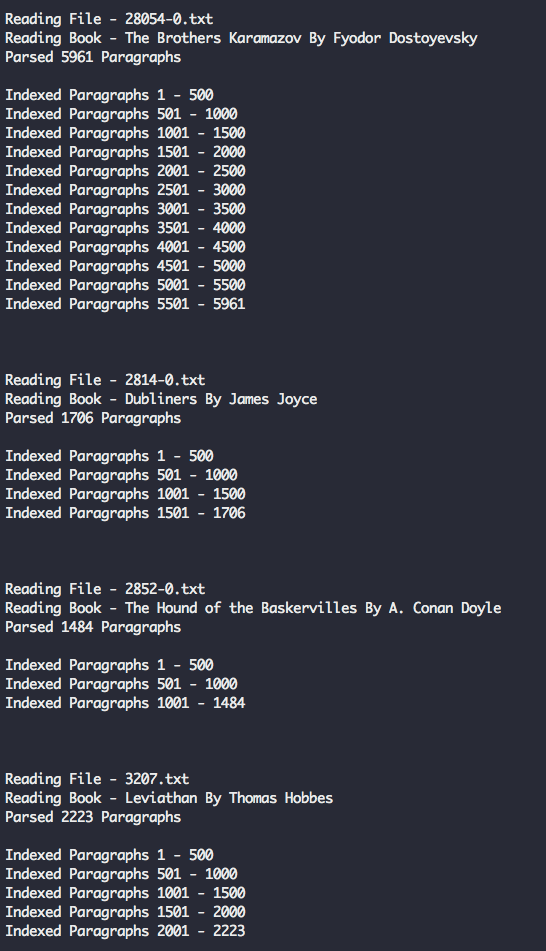
console.log(`Indexed Paragraphs ${i - 499} - ${i}`)
}
}
// Insert remainder of bulk ops array
awaitesConnection.client.bulk({ body: bulkOps })
console.log(`Indexed Paragraphs ${paragraphs.length - (bulkOps.length / 2)} - ${paragraphs.length}nnn`)
}
此函数索引书籍段落,包括作者、书名和段落元数据信息。使用bulk操作插入段落,比分别索引段落效率高很多。
批量bulk索引这些段落可以使本应用运行在低配电脑上(我只有1.7G内存),如果你有高配电脑(大于4G内容),也许不用考虑批量bulk操作。
运行docker-compose up -d --build 和 docker exec gs-api "node" "server/load_data.js" 输出如下:
5. 搜索
Elasticsearch已经灌入100本书籍数据(大约230000段落),本节做一些搜索操作。
5.0 简单http查询
首先,使用:9200/library/_search?q=text:Java&pretty , 这里使用全文本查询关键字“Java”,输入应该如下:
{
"took": 11,
"timed_out": false,
"_shards": {
"total": 5,
"successful": 5,
"skipped": 0,
"failed": 0
},
"hits": {
"total": 13,
"max_score": 14.259304,
"hits": [
{
"_index": "library",
"_type": "novel",
"_id": "p_GwFWEBaZvLlaAUdQgV",
"_score": 14.259304,
"_source": {
"author": "Charles Darwin",
"title": "On the Origin of Species",
"location": 1080,
"text": "Java, plants of, 375."
}
},
{
"_index": "library",
"_type": "novel",
"_id": "wfKwFWEBaZvLlaAUkjfk",
"_score": 10.186235,
"_source": {
"author": "Edgar Allan Poe",
"title": "The Works of Edgar Allan Poe",
"location": 827,
"text": "After many years spent in foreign travel, I sailed in the year 18-- , from the port of Batavia, in the rich and populous island of Java, on a voyage to the Archipelago of the Sunda islands. I went as passenger--having no other inducement than a kind of nervous restlessness which haunted me as a fiend."
本文来自电脑杂谈,转载请注明本文网址:
https://www.pc-fly.com/a/jisuanjixue/article-88488-9.html
-

-
刘静静
凡是在划定区域内的任何船只都是属于靶标
-
杨太尉
央视报告什么都挨骂
 在Oracle中查看所有表和字段以及表注释. 现场评论
 如果win8总是占据磁盘的100%,该怎么办
 贵阳展台搭建公司 【扬中产业发展规划√市政道路
 linux上目前装着python2.6,我想把python替换为python3
高蛋白质呀