access官方下载 免费完整版 使用Docker和Elasticsearch搭建全文本搜索引(8)
电脑杂谈 发布时间:2018-02-22 15:22:17 来源:网络整理constendOfBookIndex = book.match( /^*{3}s*END OF (THIS|THE) PROJECT GUTENBERG EBOOK.+*{3}$/m).index
// Clean book text and split into array of paragraphs
constparagraphs = book
.slice(startOfBookIndex, endOfBookIndex) // Remove Guttenberg header and footer
.split( /ns+n/g) // Split each paragraph into it's own array entry
.map( line=>line.replace( /rn/g, ' ').trim()) // Remove paragraph line breaks and whitespace
.map( line=>line.replace( /_/g, '')) // Guttenberg uses "_" to signify italics. We'll remove it, since it makes the raw text look messy.
.filter( (line) =>(line && line.length !== '')) // Remove empty lines
console.log( `Parsed ${paragraphs.length}Paragraphsn`)
return{ title, author, paragraphs }
}
此函数执行以下功能:
从文件系统中读入文件
使用正则表达式抽取书名和作者
通过定位***,来抽取书中内容
解析出段落
清洗数据,移除空行
最后返回一个包含书名、作者和段落列表的对象。
运行docker-compose up -d --build和docker exec gs-api "node" "server/load_data.js" ,输出如下:
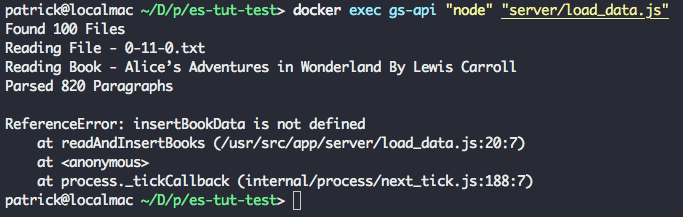
到这步,脚本顺利分理出书名和作者,脚本还会因为同样问题出错(调用还未定义的函数)。
4.5 在ES中索引数据文件
最后一步在load_data.js中添加insertBookData函数,将上一节中提取数据插入Elasticsearch索引中。
/** Bulk index the book data in Elasticsearch */
asyncfunction insertBookData(title, author, paragraphs) {
letbulkOps = [] // Array to store bulk operations
// Add an index operation for each section in the book
for( leti = 0; i < paragraphs.length; i++) {
// Describe action
bulkOps.push({ index: { _index: esConnection.index, _type: esConnection.type } })
// Add document
bulkOps.push({
author,
title,
location: i,
text: paragraphs[i]
})
if(i > 0&& i % 500=== 0) { // Do bulk insert in 500 paragraph batches
本文来自电脑杂谈,转载请注明本文网址:
https://www.pc-fly.com/a/jisuanjixue/article-88976-8.html
-

-
吴越
美国被普京打了左边脸
 360浏览器批量下载并保存图片
 网络嗅探器(视频侦探)正式版
 W764位旗舰版和纯版本系统下载
 图书销售系统参考
只能用一次