创建PK名片全能王手绘名的名片识别应用程序(如何以100%的准确性提取姓名
电脑杂谈 发布时间:2020-06-15 06:06:30 来源:网络整理
那么我们如何以100%的准确度提出名称呢?首先让我们对名称进行分类并达成共识:
名称名称的名称在小字体名称的名称周围没有小字体
提取名称时要考虑的因素包括: 字体大小名片扫描王,字符间距,字体粗细和标题周围(左右上下),只要处理了这些多个组合,就可以准确地完全提取名称.

处理方法:
进行布局分析时,分阶段加强对联通区域的提取,找到大字体的名字行
LogoParse::LogoParse(Mat& card):m_scale(SCALE_IMG_WHEN_LAYOUT_PARSE)
{
    INFO << __FUNCTION__ <<std::endl;

    assert(1==m_scale);

    cv::bitwise_not(card, m_cropped);

    //如果比BCR_5Point更大的话,会引发版面左右粘连
    rlsaInHorizon(m_cropped, BCR_10POINT/m_scale);

    //x方向不要处理,会引发左右丢字或者 名字名 孟,上面的子被处理没了
    int erosion_type = MORPH_RECT; // MORPH_RECT, MORPH_CROSS, MORPH_ELLIPSE
    int erosion_size = 2;
    Mat erosion_element = getStructuringElement( erosion_type, Size( 2*0 + 1, 2*erosion_size+1), Point( 0, erosion_size));

    cv::erode(m_cropped, m_cropped,erosion_element);
    cv::dilate(m_cropped, m_cropped,erosion_element);

    //find blobs
    {
        IplImage cropped(m_cropped);

        // get blobs and filter them using its area
        //CBlobResult blobs;

        // find blobs in image
        try {
            blobs = CBlobResult( &cropped, NULL, 0 );
        } catch (...) {
            ERROR << "CBlobResult throw exception" <<std::endl;
        }

        int N = blobs.GetNumBlobs();

        for( int j=0; j<N; j++)
        {
            CBlob *currentBlob = blobs.GetBlob(j);
            CvRect rect = currentBlob->GetBoundingBox();
            //scale it
            rect.x *= m_scale;
            rect.y *= m_scale;
            rect.width *= m_scale;
            rect.height *= m_scale;

            //过滤没有成行的版面(如长宽比不足的,小于2);简章的版面识别
            if (
                rect.height > BCR_1POINT &&
                rect.height < BCR_10POINT&&
                double(rect.width)/rect.height > 2

                )
            {
                currentBlob->FillBlob(&cropped, CV_RGB(0, 0, 0));
            }
        }

        rlsaInHorizon(m_cropped, BCR_20POINT*1.5/m_scale);
        rlsaInVertical(m_cropped, BCR_10POINT/m_scale);
        int erosion_type = MORPH_RECT; // MORPH_RECT, MORPH_CROSS, MORPH_ELLIPSE
        int erosion_size = 2;
        Mat erosion_element = getStructuringElement( erosion_type, Size( 2*erosion_size + 1, 2*erosion_size+1), Point( erosion_size, erosion_size));

        cv::erode(m_cropped, m_cropped,erosion_element);
        cv::dilate(m_cropped, m_cropped,erosion_element);

        {
            // find blobs in image
            try {
                blobs = CBlobResult( &cropped, NULL, 0 );
            } catch (...) {
                ERROR << "CBlobResult throw exception" <<std::endl;
            }

            IplImage editImage(card);
            int N = blobs.GetNumBlobs();

            for( int j=0; j<N; j++)
            {
                CBlob *currentBlob = blobs.GetBlob(j);
                CvRect rect = currentBlob->GetBoundingBox();
                //scale it
                rect.x *= m_scale;
                rect.y *= m_scale;
                rect.width *= m_scale;
                rect.height *= m_scale;

                //提取大概的大字体名字行
                if (
                    rect.height > BCR_10POINT &&
                    rect.height < BCR_20POINT &&
                    double(rect.width)/rect.height > 2.0 &&
                    double(rect.width)/rect.height < 10.0
                    )
                {
                    m_nameBox.push_back(rect);

                }
                else
                {
                    currentBlob->FillBlob(&editImage, CV_RGB(255, 255, 255));
                }
            }
        }
    }

    //尽快释放内存
    m_cropped.release();

    INFO << __FUNCTION__<< " end" <<std::endl;
}
大字体名称行可能包含Tile. 还需要对名称行进行细分,在该行中进行聚类分析,然后将分解名称和标题
std::vector<LineStatic> LineStatic::ccl_name_title() const
{
    /**
     *  case 1: NNN TTT (可归为按空格分)
     *  case 2: NNN ttt (字体高低有别且有别处有空格)
     *  case 3: N N N ttt
     */

    //字体高度分类

        此处理省去1000字
        // 输出分簇结果

        for(int i=0;i<clusters.size();i++)
        {
            BCR::Point center = clusters[i].getCenter();
            mincomplexity = std::min(mincomplexity, center.coordinate[0]);
            if (mincomplexity == center.coordinate[0]) {
                mini = clusters[i].getPoints();
                num_eng = mini.size();
            }
            else
            {
                num_chi = clusters[i].getPoints().size();
            }
            cout << clusters[i] << endl;
        }

        INFO << "TotalClustersDistance:" << BCR::KMeans::TotalClustersDistance(clusters) << endl;

        for (std::vector<BCR::Point>::iterator it = mini.begin(); it != mini.end(); it++) {
            mini_bg = std::min(mini_bg, it->coordinate[0]);
            mini_ed = std::max(mini_ed, it->coordinate[0]);
        }

        BCR::Point eng_center = clusters[0].getCenter();
        BCR::Point chi_center = clusters[1].getCenter();
        if (eng_center.coordinate[0] > chi_center.coordinate[0]) {
            std::swap(eng_center, chi_center);
        }

        title_height = eng_center.coordinate[0];
        name_height = chi_center.coordinate[0];

        title_width = eng_center.coordinate[1];
        name_width = chi_center.coordinate[1];
    }

    //高低相差大于5号字,分行
    std::vector<LineStatic> nametitle;

    double averHeightDiff = this->rect.height*0.2;

    if ((std::abs(name_height - title_height) > averHeightDiff ||
        std::abs(name_width - title_width) > averHeightDiff)
        &&
        title_height > BCR_5POINT/2 &&
        name_height > BCR_5POINT*1.5
        )
    {
        t_boxes name;
        t_boxes title;

        t_boxes::const_iterator it = words.begin();
        t_boxes::const_iterator it_pre = it;
        for (; it != words.end(); it++)
        {
            //名字字体大于title,且在空格处
            int space = it->x - it_pre->x - it_pre->width ;
            it_pre = it;

            if( std::max(it->width,it->height) < name_height - averHeightDiff  && space > BCR_5POINT/2)
            {
                break;
            }
            else
            {
                name.insert(*it);
            }
        }

        for (; it != words.end(); it++)
        {
            //名字字体大于title
            title.insert(*it);
        }

        //double check
        LineStatic nameL(name);
        LineStatic titleL(title);
        if (nameL.rect.height - titleL.rect.height > BCR_DOT_POINT*2) {
            nametitle.push_back(nameL);
            nametitle.push_back(titleL);
        }
    }

    if (0==nametitle.size()) {
        nametitle.push_back(words);
    }

    return nametitle;

}
分析OCR结果并找到最类似于名称的名称框

        //(1): first name
        if (double(line.rect.width) / line.rect.height < 5.0  && strlen(name) > 1) {
            std::string firstCharactor(name,3);
            char* pos = strstr(ALL_CHINESE_FIRSTNAME, firstCharactor.c_str());
            if (pos) {
                weight += 10000;
                tprintf("Chinese Name checked %s\n", firstCharactor.c_str());
            }
        }
对联通区域进行这样的提取,重新细分和重新确认后,您始终可以在名片中找到最类似于该名称的内容. 整个识别过程与人脑看名字的想法相同. 首先缩小范围名片扫描王,关注重点,然后再认识.
识别结果是这样的,有真实的图片,以下是测试结果图片:
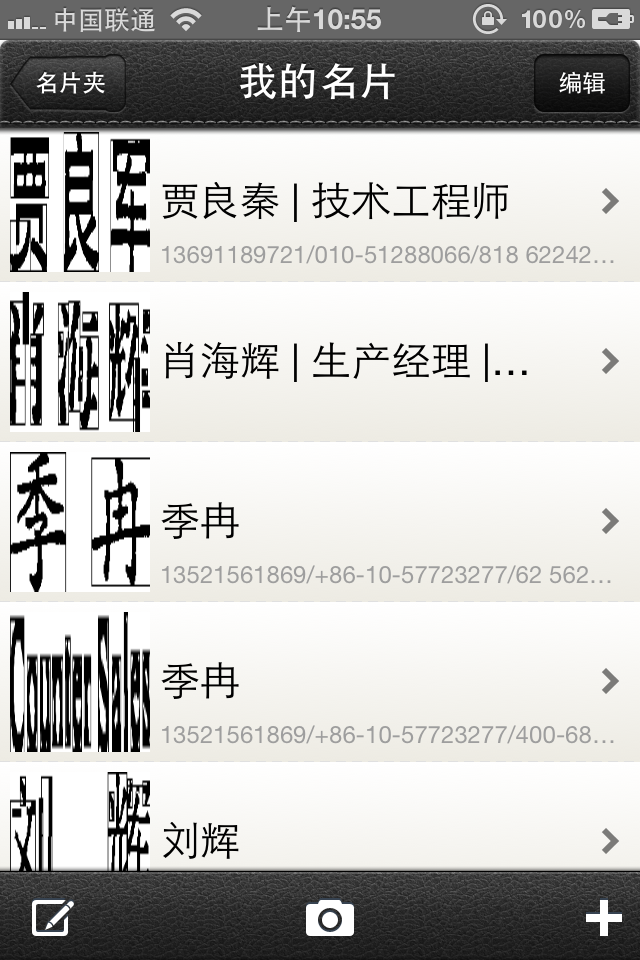
名称提取功能刚刚得到改进,该应用程序仍在升级中!如果要测试,可以从App Store下载. 名片扫描仪ScanZen
本文来自电脑杂谈,转载请注明本文网址:
https://www.pc-fly.com/a/ruanjian/article-245859-1.html
相关阅读
发表评论 请自觉遵守互联网相关的政策法规,严禁发布、暴力、反动的言论
-

-
齐孝公吕昭
换言之你10万存银行一年就是购买力变成99900
每日福利
 战国传承3出招表_战国传承3 影连 连招_战国传承3下载
 在安装Office软件时如何选择Office版本
 如何制作简单的书架如何使用纸箱制作书架
 天正建筑2014破解教程(注册机破解和过期补丁破解)
热点图片
面