使用Google API提取名片信息
电脑杂谈 发布时间:2020-04-26 04:28:37 来源:网络整理
我们每个人都会或多或少使用名片. 但是,如果名片数量很大,则管理它们将变得非常麻烦. 因此,我生成了本文的案例来对其进行管理.
在这里,我将用手机为每张名片拍照,并按照以下过程进行处理:
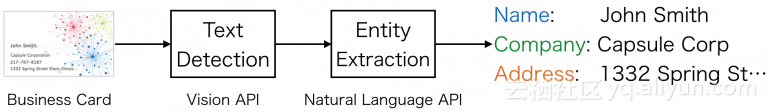
将获得的名片图像提供给我们的应用程序,并提取人员的姓名,公司名称,地址和其他信息. 在这里名片识别 api,我使用Google Vision API和自然语言API,因为这两个API简单易用,并且性能也非常好.
我使用Python编写应用程序以调用Google Vision API和自然语言API.
第0步: 准备工作
第1步: 使用Google Vision API识别文本
第2步: 使用自然语言API提取姓名,公司名称和地址信息
第3步: 集成第1步和第2步
在开始编写应用程序之前,我们需要安装必要的类库,下载配置并设置API的键值. 通过此链接,您可以设置Google API密钥.

执行命令行以安装类库.
$ pip install requests
$ pip install pyyaml
这里我已经预先准备了资源库. 也可以从下面的链接下载.
将Google API密钥写入配置文件(插件/ config / google.yaml).
首先,打开google.yaml并将您的API密钥替换为xxx.
token: xxx视觉API简介
借助强大的机器学习模型,Google Vision API允许您编写自己的图像识别应用程序. Vision API具有以下功能:
Vision API每月有1,000个免费请求.
在这里,我们编写了一个Python脚本来使用Vision API. 将以下代码另存为plugins / apis / vision.py. 在这里名片识别 api,我们要使用UTF-8编码.

# -*- coding: utf-8 -*-
import base64
import requests
def detect_text(image_file, access_token=None):
    with open(image_file, 'rb') as image:
        base64_image = base64.b64encode(image.read()).decode()
    url = 'https://vision.googleapis.com/v1/images:annotate?key={}'.format(access_token)
    header = {'Content-Type': 'application/json'}
    body = {
        'requests': [{
            'image': {
                'content': base64_image,
            },
            'features': [{
                'type': 'TEXT_DETECTION',
                'maxResults': 1,
            }]
        }]
    }
    response = requests.post(url, headers=header, json=body).json()
    text = response['responses'][0]['textAnnotations'][0]['description'] if len(response['responses'][0]) > 0 else ''
    return text
输入图像文件的路径和detect_text函数的API密钥,我们可以获取图像文件中的文本信息
首先,将脚本文件移动到plugins / tests文件夹中. 已经有一个test_vision.py文件. 在test_vision.py中,编写调用detect_text函数的测试用例. 如果操作正常,我们可以在图像中获取文本信息.
使用下面的example_en.png名片作为输入来运行脚本.
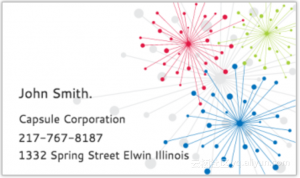
$ python test_vision.py data/example_en.png输出结果
John Smith.
Capsule Corporation
217-767-8187
1332 Spring Street Elwin Illinois
第2步,使用自然语言API提取姓名,公司名称和地址信息
自然语言API简介

自然语言API提供了强大的机器学习模型,以REST API的形式识别文本结构及其含义. 自然语言API具有以下功能:
Vision API每月有5000个免费请求.
同样,我们编写了一个Python脚本来调用Natural Language API. 将脚本另存为plugins / apis / language.py. 请注意,使用的是UTF-8编码.
# -*- coding: utf-8 -*-
import requests
def extract_entities(text, access_token=None):
    url = 'https://language.googleapis.com/v1beta1/documents:analyzeEntities?key={}'.format(access_token)
    header = {'Content-Type': 'application/json'}
    body = {
        "document": {
            "type": "PLAIN_TEXT",
            "language": "EN",
            "content": text
        },
        "encodingType": "UTF8"
    }
    response = requests.post(url, headers=header, json=body).json()
    return response
def extract_required_entities(text, access_token=None):
    entities = extract_entities(text, access_token)
    required_entities = {'ORGANIZATION': '', 'PERSON': '', 'LOCATION': ''}
    for entity in entities['entities']:
        t = entity['type']
        if t in required_entities:
            required_entities[t] += entity['name']
    return required_entities
将文本数据和API密钥作为参数放入extract_entities函数中,可以提取不同的实体信息. 而且我们只需要公司名称,个人名称,位置信息. extract_required_entities函数用于过滤掉这些必需的内容.
类似地,将脚本文件移动到plugins / tests文件夹. 我们将看到一个test_language.py文件. 在test_language.py中,编写调用extract_required_entities函数的测试用例.
在这里,我使用准备好的example_en.txt文本文件作为输入来运行脚本. example_en.txt文本文件包含上一步的输出.
$ python test_language.py data/example.txt输出结果
{'LOCATION': 'Spring Street Elwin Illinois', 'PERSON': 'John Smith', 'ORGANIZATION': 'Capsule Corporation'}
最后,我们编写了另一个脚本来集成Vision API和Natural Language API.
编写脚本以集成Vision API和Natural Language API. 另存为插件/apis/integration.py. 在这里,我们要使用UTF-8编码.
# -*- coding: utf-8 -*-
from .language import extract_required_entities
from .vision import detect_text
def extract_entities_from_img(img_path, access_token):
    text = detect_text(img_path, access_token)
    entities = extract_required_entities(text, access_token)
    return entities
通过将图像文件路径和API密钥作为参数输入到extract_entities_from_img中,可以从名片图像中提取上述信息数据.
首先,将脚本文件移动到plugins / tests文件夹中. 已经有一个test_integration.py文件. 在test_integration.py中,编写一个调用extract_entities_from_img的测试.
使用图像文件example_en.png作为输入数据运行脚本.
$ python test_integration.py data/example_en.png输出结果
{'LOCATION': 'Spring Street Elwin Illinois', 'PERSON': 'John Smith', 'ORGANIZATION': 'Capsule Corporation'}在上面,我们编写了一个简单的应用程序,用于使用Google Vision API和Natural Language API提取名片信息. 但是,这只是一个简单的原型,我稍后会对其进行改进以使其更加完美.
上面是翻译
文章最初的标题为“使用Google API从名片中提取信息”,作者: HIRONSAN
本文是简体翻译. 有关更多详细内容,请参阅原文
本文来自电脑杂谈,转载请注明本文网址:
https://www.pc-fly.com/a/ruanjian/article-189139-1.html
-
 林钰杰
 局域网管家监控 V2014.05 绿色破解版最新无限制版测试可用[联网软件]
 做用ip地址干嘛用 网上找赚钱靠谱吗?正规网络是怎么做的
 游戏充值平台代理加盟 【图】牛大王平台新款游戏 拼三大王 诚招总代理锦州太和
 超级兔子杀毒_无法连接虚拟磁盘服务_超级兔子虚拟磁盘