BeautifulSoup4的安装及使用
电脑杂谈 发布时间:2020-03-19 03:02:09 来源:网络整理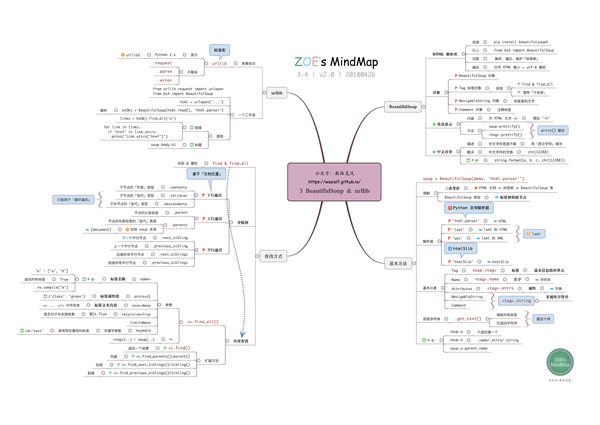
如:soup.title
#
soup.p
#
The Dormouse's story
soup.a(注:仅仅返回第一个结果)

# Elsie
soup.find_all('a') (find_all 可以返回所有)
# [Elsie,
# Lacie,
# Tillie]
find还可以按属性查找

soup.find(id="link3")
# Tillie
要取某个标签的某个属性beautifulsoup怎么用,可用变量有 find_all,get
for link insoup.find_all('a'):
print(link.get('href'))
#

#
#
要取html文件中的所有文本beautifulsoup怎么用,可使用get_text()
print(soup.get_text())
# TheDormouse's story
# TheDormouse's story

# Once upona time there were three little sisters; and their names were
#Elsie,
# Lacieand
#Tillie;
# and theylived at the bottom of a well.
# ...
如果是打开html文件,语句可用:
soup =BeautifulSoup(open("index.html"))
BeautifulSoup中的Object
本文来自电脑杂谈,转载请注明本文网址:
https://www.pc-fly.com/a/jisuanjixue/article-144654-1.html
相关阅读
发表评论 请自觉遵守互联网相关的政策法规,严禁发布、暴力、反动的言论
-

-
李晓静
对中国大部分地区来说问题不是环保
每日福利
 awk Oneliner(2)文本替换
 现代林业与生态林业【新闻资讯】河阴镇党委副赵青说:生态农业旅
 tiobe编程语言排行榜 2012 4 武汉千锋Java培训机构
 操作方法:重新安装系统教程,教您如何重新安装win10系统。
热点图片
文化上